
PEFT documentation
Fully Sharded Data Parallel
Fully Sharded Data Parallel
Fully sharded data parallel (FSDP) is developed for distributed training of large pretrained models up to 1T parameters. FSDP achieves this by sharding the model parameters, gradients, and optimizer states across data parallel processes and it can also offload sharded model parameters to a CPU. The memory efficiency afforded by FSDP allows you to scale training to larger batch or model sizes.
PEFT supports FSDP1 and PyTorch FSDP2. You can configure FSDP through Transformers Trainer or use it directly in a PyTorch training loop.
FSDP2 with Transformers
Use PyTorch 2.6 or newer and current versions of Transformers, Accelerate, TRL, and PEFT. The SFT example uses SFTTrainer. Here is a typical FSDP2 configuration:
{
  "fsdp": true,
  "fsdp_config": {
    "version": 2,
    "reshard_after_forward": true,
    "auto_wrap_policy": "TRANSFORMER_BASED_WRAP",
    "cpu_ram_efficient_loading": true,
    "state_dict_type": "SHARDED_STATE_DICT",
    "activation_checkpointing": false
  }
}
TRANSFORMER_BASED_WRAP uses the model’s transformer-layer definitions. reshard_after_forward releases gathered parameters after each forward pass. FSDP2 shards individual parameters, so it does not use FSDP1’s use_orig_params setting. See the Transformers FSDP guide for more configuration options.
Edit the model, dataset, and training options in the example’s fsdp2_config.json. From examples/sft, launch one process per GPU:
torchrun --standalone --nproc_per_node=2 train.py configs/fsdp2_config.json
On GPUs without BF16 support, set "bf16": false and "fp16": true in the JSON file.
With PEFT versions earlier than v0.22, keep activation_checkpointing set to false to avoid empty adapter exports. PEFT v0.22 includes the adapter export fix.
Save and resume
To resume training, keep the same FSDP configuration and set "resume_from_checkpoint": "path/to/checkpoint-N" in the JSON file. Training checkpoints contain sharded model and optimizer states.
At the end of training, the example gathers a full state dictionary before exporting the adapter:
if trainer.is_fsdp_enabled:
    trainer.accelerator.state.fsdp_plugin.set_state_dict_type("FULL_STATE_DICT")
trainer.save_model()
All ranks must participate in the gather; only the main process writes the adapter files. Gathering the full state dictionary temporarily increases memory use.
For inference, load the exported adapter:
import torch

from peft import AutoPeftModelForCausalLM

model = AutoPeftModelForCausalLM.from_pretrained("qwen-sft-lora-fsdp2", dtype=torch.float32)
If the SFT run added tokens that grew the base model’s embeddings, match the training-time embedding size before loading the adapter. The SFT example pads grown embeddings to a multiple of 8:
import torch
from transformers import AutoModelForCausalLM, AutoTokenizer

from peft import PeftConfig, PeftModel

adapter_path = "qwen-sft-lora-fsdp2"
config = PeftConfig.from_pretrained(adapter_path)
tokenizer = AutoTokenizer.from_pretrained(adapter_path)
base_model = AutoModelForCausalLM.from_pretrained(config.base_model_name_or_path, dtype=torch.float32)
# Match the SFT example: grow the embeddings if needed, but never shrink them.
if len(tokenizer) > base_model.get_input_embeddings().num_embeddings:
    base_model.resize_token_embeddings(len(tokenizer), pad_to_multiple_of=8)
model = PeftModel.from_pretrained(base_model, adapter_path)
FSDP1 with Accelerate
This section uses the SFT training script to fine-tune Llama-70B with LoRA and FSDP1 on 8xH100 80GB GPUs on a single machine. You can scale to multiple machines by changing the Accelerate config.
Configuration
Start by running the following command to create a FSDP configuration file with 🤗 Accelerate. The --config_file flag allows you to save the configuration file to a specific location, otherwise it is saved as a default_config.yaml file in the 🤗 Accelerate cache.
The configuration file is used to set the default options when you launch the training script.
accelerate config --config_file fsdp_config.yaml
You’ll be asked a few questions about your setup, and configure the following arguments. In this example, you’ll answer the questionnaire as shown in the image below.
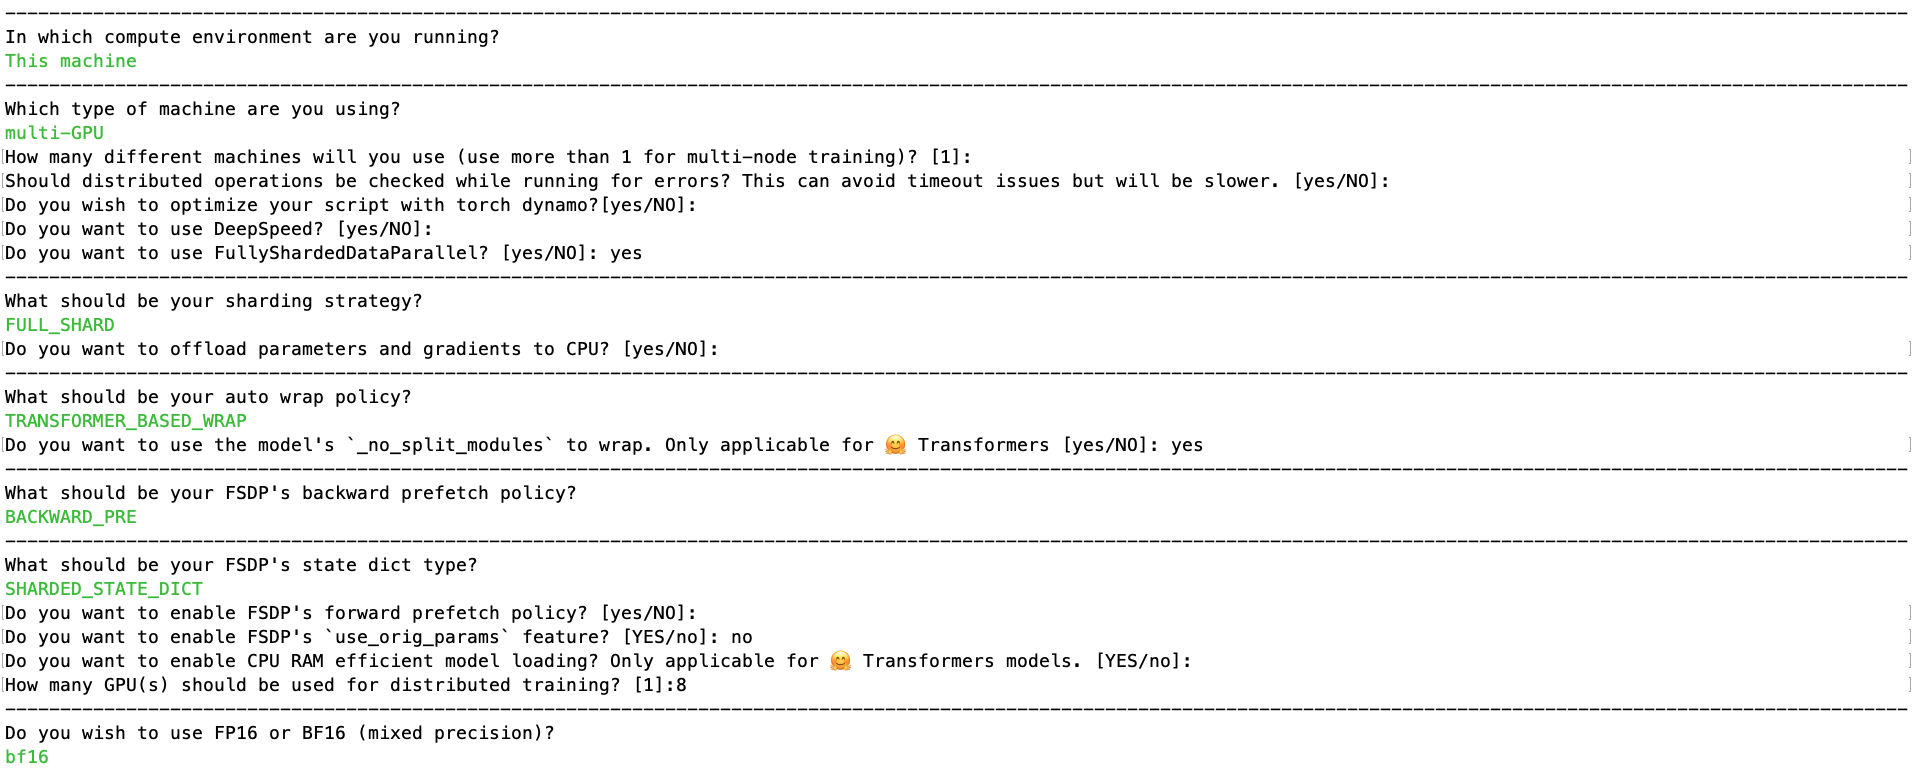
Once this is done, the corresponding config should look like below and you can find it in config folder at fsdp_config.yaml:
compute_environment: LOCAL_MACHINE
debug: false
distributed_type: FSDP
downcast_bf16: 'no'
fsdp_config:
  fsdp_version: 1
  fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP
  fsdp_backward_prefetch: BACKWARD_PRE
  fsdp_cpu_ram_efficient_loading: true
  fsdp_forward_prefetch: false
  fsdp_offload_params: false
  fsdp_sharding_strategy: FULL_SHARD
  fsdp_state_dict_type: SHARDED_STATE_DICT
  fsdp_sync_module_states: true
  fsdp_use_orig_params: false
machine_rank: 0
main_training_function: main
mixed_precision: bf16
num_machines: 1
num_processes: 8
rdzv_backend: static
same_network: true
tpu_env: []
tpu_use_cluster: false
tpu_use_sudo: false
use_cpu: false
Launch command
The launch command is available at run_peft_fsdp.sh and it is also shown below:
accelerate launch --config_file "configs/fsdp_config.yaml"  train.py \
--seed 100 \
--model_name_or_path "meta-llama/Llama-2-70b-hf" \
--dataset_name "smangrul/ultrachat-10k-chatml" \
--chat_template_format "chatml" \
--add_special_tokens False \
--append_concat_token False \
--splits "train,test" \
--max_length 2048 \
--num_train_epochs 1 \
--logging_steps 5 \
--log_level "info" \
--logging_strategy "steps" \
--eval_strategy "epoch" \
--save_strategy "epoch" \
--push_to_hub \
--hub_private_repo True \
--hub_strategy "every_save" \
--bf16 True \
--packing True \
--learning_rate 1e-4 \
--lr_scheduler_type "cosine" \
--weight_decay 1e-4 \
--warmup_steps 0 \
--max_grad_norm 1.0 \
--output_dir "llama-sft-lora-fsdp" \
--per_device_train_batch_size 8 \
--per_device_eval_batch_size 8 \
--gradient_accumulation_steps 4 \
--gradient_checkpointing True \
--use_reentrant False \
--dataset_text_field "content" \
--use_flash_attn True \
--use_peft_lora True \
--lora_r 8 \
--lora_alpha 16 \
--lora_dropout 0.1 \
--lora_target_modules "all-linear" \
--use_4bit_quantization False
Notice that we are using LoRA with rank=8, alpha=16 and targeting all linear layers. We are passing the FSDP config file and finetuning the 70B Llama model on a subset of the ultrachat dataset.
The important parts
Let’s dive a little deeper into the script so you can see what’s going on, and understand how it works.
The first thing to know is that the script uses FSDP for distributed training as the FSDP config has been passed. The SFTTrainer class handles all the heavy lifting of creating PEFT model using the peft config that is passed. After that when you call trainer.train(), Trainer internally uses 🤗 Accelerate to prepare model, optimizer and trainer using the FSDP config to create FSDP wrapped model which is then trained. The main code snippet is below:
# trainer
trainer = SFTTrainer(
    model=model,
    processing_class=tokenizer,
    args=training_args,
    train_dataset=train_dataset,
    eval_dataset=eval_dataset,
    peft_config=peft_config,
)
trainer.accelerator.print(f"{trainer.model}")
if hasattr(trainer.model, "print_healthcheck"):
    trainer.model.print_healthcheck()

# train
checkpoint = None
if training_args.resume_from_checkpoint is not None:
    checkpoint = training_args.resume_from_checkpoint
trainer.train(resume_from_checkpoint=checkpoint)

# saving final model
if trainer.is_fsdp_enabled:
    trainer.accelerator.state.fsdp_plugin.set_state_dict_type("FULL_STATE_DICT")
trainer.save_model()
With FSDP1, use_orig_params=False reduces memory use by wrapping trainable and frozen parameters separately. Current Transformers Trainer installs PEFT’s fsdp_auto_wrap_policy for this case; the example does not need to set it manually. A custom Accelerate FSDP1 training loop must set that policy before preparing the model. This flat-parameter wrapping requirement does not apply to FSDP2.
Memory usage
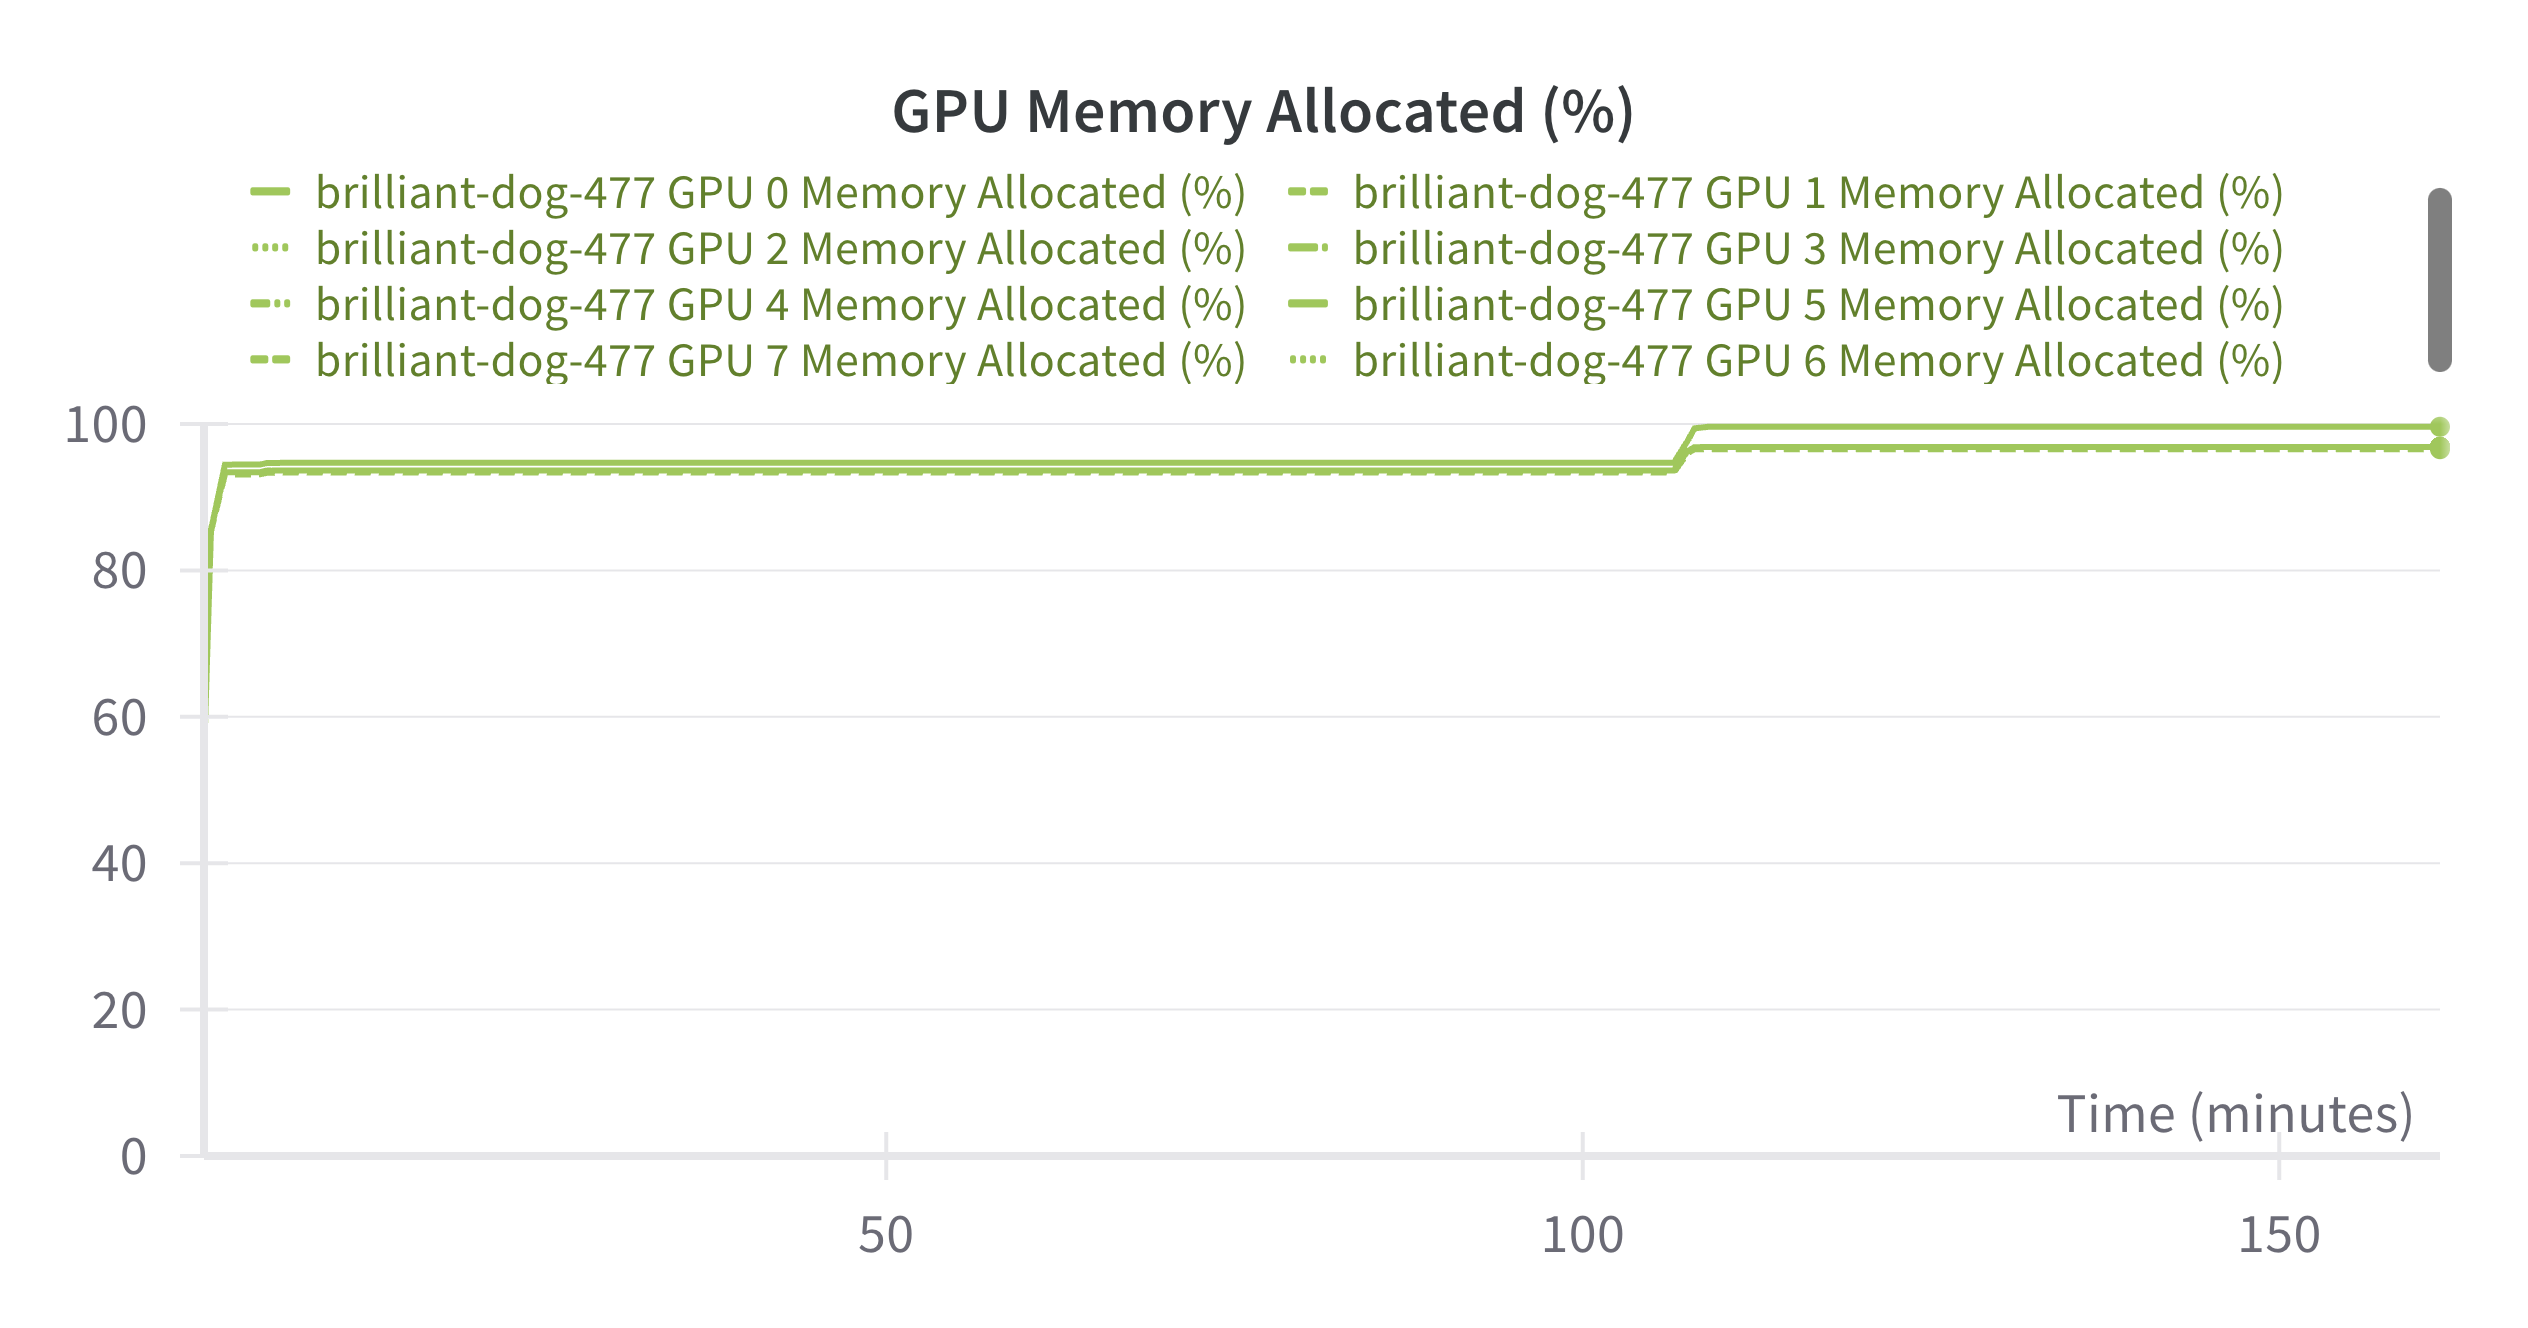
In the above example, the memory consumed per GPU is 72-80 GB (90-98%) as seen in the screenshot below. The slight increase in GPU memory at the end is when saving the model using FULL_STATE_DICT state dict type instead of the SHARDED_STATE_DICT so that the model has adapter weights that can be loaded normally with from_pretrained method during inference:
FSDP1 with QLoRA
In this section, we will look at how to use QLoRA and FSDP for finetuning 70B llama model on 2X24GB GPUs. Answer.AI in collaboration with bitsandbytes and Hugging Face 🤗 open sourced code enabling the usage of FSDP+QLoRA and explained the whole process in their insightful blogpost You can now train a 70b language model at home. This is now integrated in Hugging Face ecosystem.
Use current PEFT, Transformers, TRL and Accelerate with bitsandbytes>=0.43.3. For this FSDP1 configuration, set fsdp_cpu_ram_efficient_loading=true, fsdp_use_orig_params=false and fsdp_offload_params=true (CPU offloading). The config is available at fsdp_config_qlora.yaml:
compute_environment: LOCAL_MACHINE
debug: false
distributed_type: FSDP
downcast_bf16: 'no'
fsdp_config:
  fsdp_version: 1
  fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP
  fsdp_backward_prefetch: BACKWARD_PRE
  fsdp_cpu_ram_efficient_loading: true
  fsdp_forward_prefetch: false
  fsdp_offload_params: true
  fsdp_sharding_strategy: FULL_SHARD
  fsdp_state_dict_type: SHARDED_STATE_DICT
  fsdp_sync_module_states: true
  fsdp_use_orig_params: false
machine_rank: 0
main_training_function: main
mixed_precision: 'no'
num_machines: 1
num_processes: 2
rdzv_backend: static
same_network: true
tpu_env: []
tpu_use_cluster: false
tpu_use_sudo: false
use_cpu: false
Launch command is given below which is available at run_peft_qlora_fsdp.sh:
accelerate launch --config_file "configs/fsdp_config_qlora.yaml"  train.py \
--seed 100 \
--model_name_or_path "meta-llama/Llama-2-70b-hf" \
--dataset_name "smangrul/ultrachat-10k-chatml" \
--chat_template_format "chatml" \
--add_special_tokens False \
--append_concat_token False \
--splits "train,test" \
--max_length 2048 \
--num_train_epochs 1 \
--logging_steps 5 \
--log_level "info" \
--logging_strategy "steps" \
--eval_strategy "epoch" \
--save_strategy "epoch" \
--push_to_hub \
--hub_private_repo True \
--hub_strategy "every_save" \
--bf16 True \
--packing True \
--learning_rate 1e-4 \
--lr_scheduler_type "cosine" \
--weight_decay 1e-4 \
--warmup_steps 0 \
--max_grad_norm 1.0 \
--output_dir "llama-sft-qlora-fsdp" \
--per_device_train_batch_size 2 \
--per_device_eval_batch_size 2 \
--gradient_accumulation_steps 2 \
--gradient_checkpointing True \
--use_reentrant True \
--dataset_text_field "content" \
--use_flash_attn True \
--use_peft_lora True \
--lora_r 8 \
--lora_alpha 16 \
--lora_dropout 0.1 \
--lora_target_modules "all-linear" \
--use_4bit_quantization True \
--use_nested_quant True \
--bnb_4bit_compute_dtype "bfloat16" \
--bnb_4bit_quant_storage_dtype "bfloat16"
Notice the new argument being passed, bnb_4bit_quant_storage_dtype, which denotes the data type for packing the 4-bit parameters. For example, when it is set to bfloat16, 16/4 = 4 4-bit params are packed together post quantization. When using mixed precision training with bfloat16, bnb_4bit_quant_storage_dtype can be either bfloat16 for pure bfloat16 finetuning, or float32 for automatic mixed precision (this consumes more GPU memory). When using mixed precision training with float16, bnb_4bit_quant_storage_dtype should be set to float32 for stable automatic mixed precision training.
In terms of training code, the important code changes are:
...

bnb_config = BitsAndBytesConfig(
    load_in_4bit=args.use_4bit_quantization,
    bnb_4bit_quant_type=args.bnb_4bit_quant_type,
    bnb_4bit_compute_dtype=compute_dtype,
    bnb_4bit_use_double_quant=args.use_nested_quant,
+   bnb_4bit_quant_storage=quant_storage_dtype,
)

...

model = AutoModelForCausalLM.from_pretrained(
    args.model_name_or_path,
    quantization_config=bnb_config,
    trust_remote_code=True,
    attn_implementation="flash_attention_2" if args.use_flash_attn else "eager",
+   dtype=quant_storage_dtype or torch.float32,
)
Notice that dtype for AutoModelForCausalLM is same as the bnb_4bit_quant_storage data type. That’s it. Everything else is handled by Trainer and TRL.
Memory usage
In the above example, the memory consumed per GPU is 19.6 GB while CPU RAM usage is around 107 GB. When disabling CPU offloading, the GPU memory usage is 35.6 GB/ GPU. Therefore, what took 16X80GB GPUs for full finetuning, 8X80GB GPUs with FSDP+LoRA, and a couple of 80GB GPUs with DDP+QLoRA, now requires 2X24GB GPUs. This makes finetuning of large models more accessible.
More resources
You can also refer the llama-recipes repo and Getting started with Llama guide on how to finetune using FSDP and PEFT.
Caveats
- With FSDP1 (the Accelerate FSDP integration used above), merging is unsupported and raises an error. With FSDP2 (
fully_shard),merge_adapter()andunmerge_adapter()reach the sharded parameters: merging plain LoRA (includingsafe_merge) onLinear,Embeddingand convolutional base layers works, as does DoRA and (IA)^3 onLinear. Other adapters or layer combinations are not covered by these methods and either raise an error or can silently fail to merge, so verify the result before relying on it. One known example is a DoRA layer whosebase_layeris wrapped by an FSDP2 module of its own, which raises. - Passing
modules_to_saveconfig parameter to is untested at present. - GPU Memory saving when using CPU Offloading is untested at present.
- When using FSDP+QLoRA,
paged_adamw_8bitcurrently results in an error when saving a checkpoint. - DoRA training with FSDP should work (albeit at lower speed than LoRA). If combined with bitsandbytes (QDoRA), 4-bit quantization should also work, but 8-bit quantization has known issues and is not recommended.
- With FSDP2,
set_adapter()andset_requires_grad()reshard the FSDP2 modules inside the PeftModel, including thePeftModelitself, so thatrequires_gradchanges reach the sharded parameters. - Exiting
disable_adapter()only does so if FSDP2 replaced the registered parameter objects inside it, as a forward does with sharded parameters, or if re-enabling changesrequires_gradfrom what it was on entry. merge_adapter()andunmerge_adapter()reshard the FSDP2 modules as well, so that the merge and the unmerge reach the sharded parameters; without the reshard, a merge would end up in the unsharded parameters that a forward left registered, and the next reshard would drop it. The merge itself is written in place into the sharded parameters.- FSDP2 modules that shard parameters of a merged adapter layer are not resharded by
set_adapter()andset_requires_grad(), so unmerge before calling these methods. Enteringdisable_adapter()under FSDP2 unmerges merged layers automatically, so that the unmerge reaches the sharded parameters; the merge therefore does not survive the context. - With
reshard_after_forward=False, or for the root module with the defaultNone, the next forward all-gathers again. - FSDP2 modules that wrap the
PeftModelare not resharded; callreshard()on them before these methods. - Prompt learning methods and adaption prompt are not covered yet.
- With FSDP2/HSDP, call
get_peft_model_state_dict()orsave_pretrained()on every participating rank: gathering distributed adapter tensors is a collective. Forsave_pretrained(), passis_main_process=Trueonly on the writing rank. Only selected adapter entries (including explicitly requested embeddings ormodules_to_save) are gathered; unselected base-model weights remain sharded.