
Long-form texts read aloud for speech recording.
AI & ML interests
Improving voice AI accuracy for code-switched English-Hebrew for English-speaking immigrants in Israel and the Jewish world. Models: ASR (focus), TTS ( POC / experimentary).
Recent Activity
View all activity
Organization Card

Hebrish · היבריש
Dictation that gets the Hebrew words right.
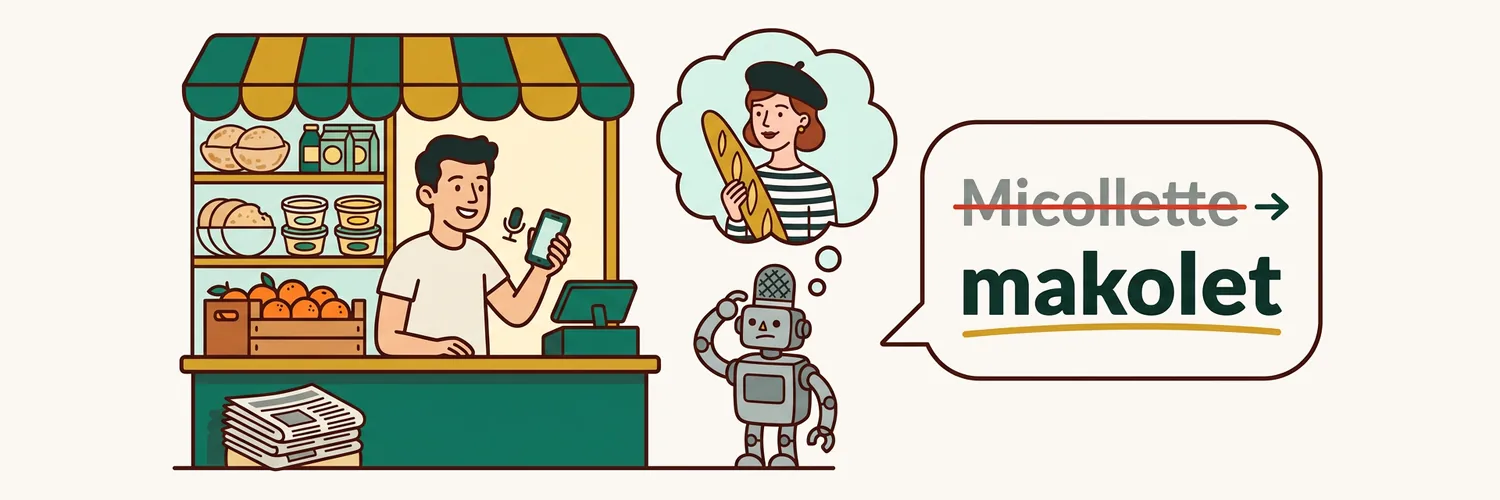
Ordinary dictation hears makolet and writes "Micollette". Hebrish writes the Hebrew word.
Hebrish builds open speech tools for code-switched English–Hebrew, for English-speaking immigrants in Israel and users throughout the Jewish world: speech recognition (ASR) that writes the Hebrew words correctly, and speech synthesis (TTS) that says them correctly. It is a one-person, not-for-profit project by Daniel Rosehill, and its models and data are open.
- Models: see them all on one page in the Hebrish Models Space.
- Speech recognition (ASR):
- Sabich (Rolling), the default in the apps since 2026-11-02: Sabich trained further from its own weights on each new batch of recordings.
- Sabich (Stable), the established release: code-switching plus tech vocabulary. Try either in your browser in the Sabich demo. The Sabich line comes in variants for every size of device: Qwen3-ASR-1.7B and Canary-Qwen-2.5B for desktop GPUs, Parakeet-110M for small devices, and asr4all-S and -M for wearables.
- Jachnun: code-switching only.
- Shakshuka: streaming, so the words appear while you speak.
- Whisper Hebrish: Whisper fine-tunes, where the project started.
- On-device builds (GGUF, ONNX, sherpa-onnx, MLX) are in
-<format>repos. Which model should I use?
- Speech synthesis (TTS):
- Meorav: code-switching text-to-speech, a Qwen3-TTS fine-tune that reads code-switched English aloud and pronounces the Hebrew words in it correctly. Meorav PoC-1 is the first checkpoint: experimental, open (CC BY-NC 4.0), no benchmark yet. Training code: Meorav-TTS.
- A token classifier that finds romanized Hebrew words in English text, for text-to-speech.
- Data: read-aloud code-switching sentences and a frozen benchmark, scored by Hebrew-term recall on a clean subset. Also every Israeli street name (national list with English names from OpenStreetMap), the vocabulary source for street sentences. Results: hebrish.app/benchmarks.
- Apps: Hebrish runs the models on-device on Android, Linux and Windows.
Everything in one place, including repos still on Daniel's personal account: the Hebrish collection.
Website: hebrish.app · GitHub: Hebrish-ASR
spaces 9
pinned
Running
Hebrish: try Sabich
🥙
English dictation with Hebrew words, tech terms and numbers
pinned
Running
Hebrish Models
🥙
Every Hebrish English-Hebrew code-switching speech model
pinned
Running
Hebrish: try Jachnun
🫓
English dictation that gets the Hebrew words right
Running
Pipeline Scratchpad
🧪
Hebrish speech-to-text pipelines, current and explored
Running
Meorav samples
🔊
Listening samples for Hebrish/Meorav
models 35

Hebrish/Falafel-Parakeet-110M-sherpa-onnx-int8
Automatic Speech Recognition • Updated
Hebrish/Falafel-sherpa-onnx-int8
Automatic Speech Recognition • Updated
Hebrish/Falafel-Parakeet-110M
Automatic Speech Recognition • Updated
Hebrish/Falafel
Automatic Speech Recognition • Updated
Hebrish/Sabich-Rolling
Automatic Speech Recognition • Updated • 222
Hebrish/Sabich-Rolling-ONNX
Updated • 1
Hebrish/Sabich-Rolling-sherpa-onnx-int8
Automatic Speech Recognition • Updated
Hebrish/Sabich
Automatic Speech Recognition • Updated • 478 • 1
Hebrish/Sabich-Parakeet-110M-GGUF
Automatic Speech Recognition • 0.1B • Updated • 3
Hebrish/Sabich-Parakeet-110M-sherpa-onnx-int8
Automatic Speech Recognition • Updated
datasets 92
Hebrish/Hebrish-TTS-Voice-Recordings
Updated • 22.2k
Hebrish/Israeli-Business-Sentences
Viewer • Updated • 259 • 46
Hebrish/Model-Iterations
Viewer • Updated • 31 • 65
Hebrish/Functional-GI-Sentences
Viewer • Updated • 1.11k • 85
Hebrish/Israeli-Street-Sentences
Viewer • Updated • 4.24k • 90
Hebrish/Open-Source-Sentences
Viewer • Updated • 1.48k • 87
Hebrish/Spelled-Out-Sentences
Viewer • Updated • 674 • 60
Hebrish/AI-Model-Sentences
Viewer • Updated • 1.17k • 80
Hebrish/Claude-Dictations
Viewer • Updated • 1.22k • 70
Hebrish/API-Ops-Sentences
Viewer • Updated • 380 • 68